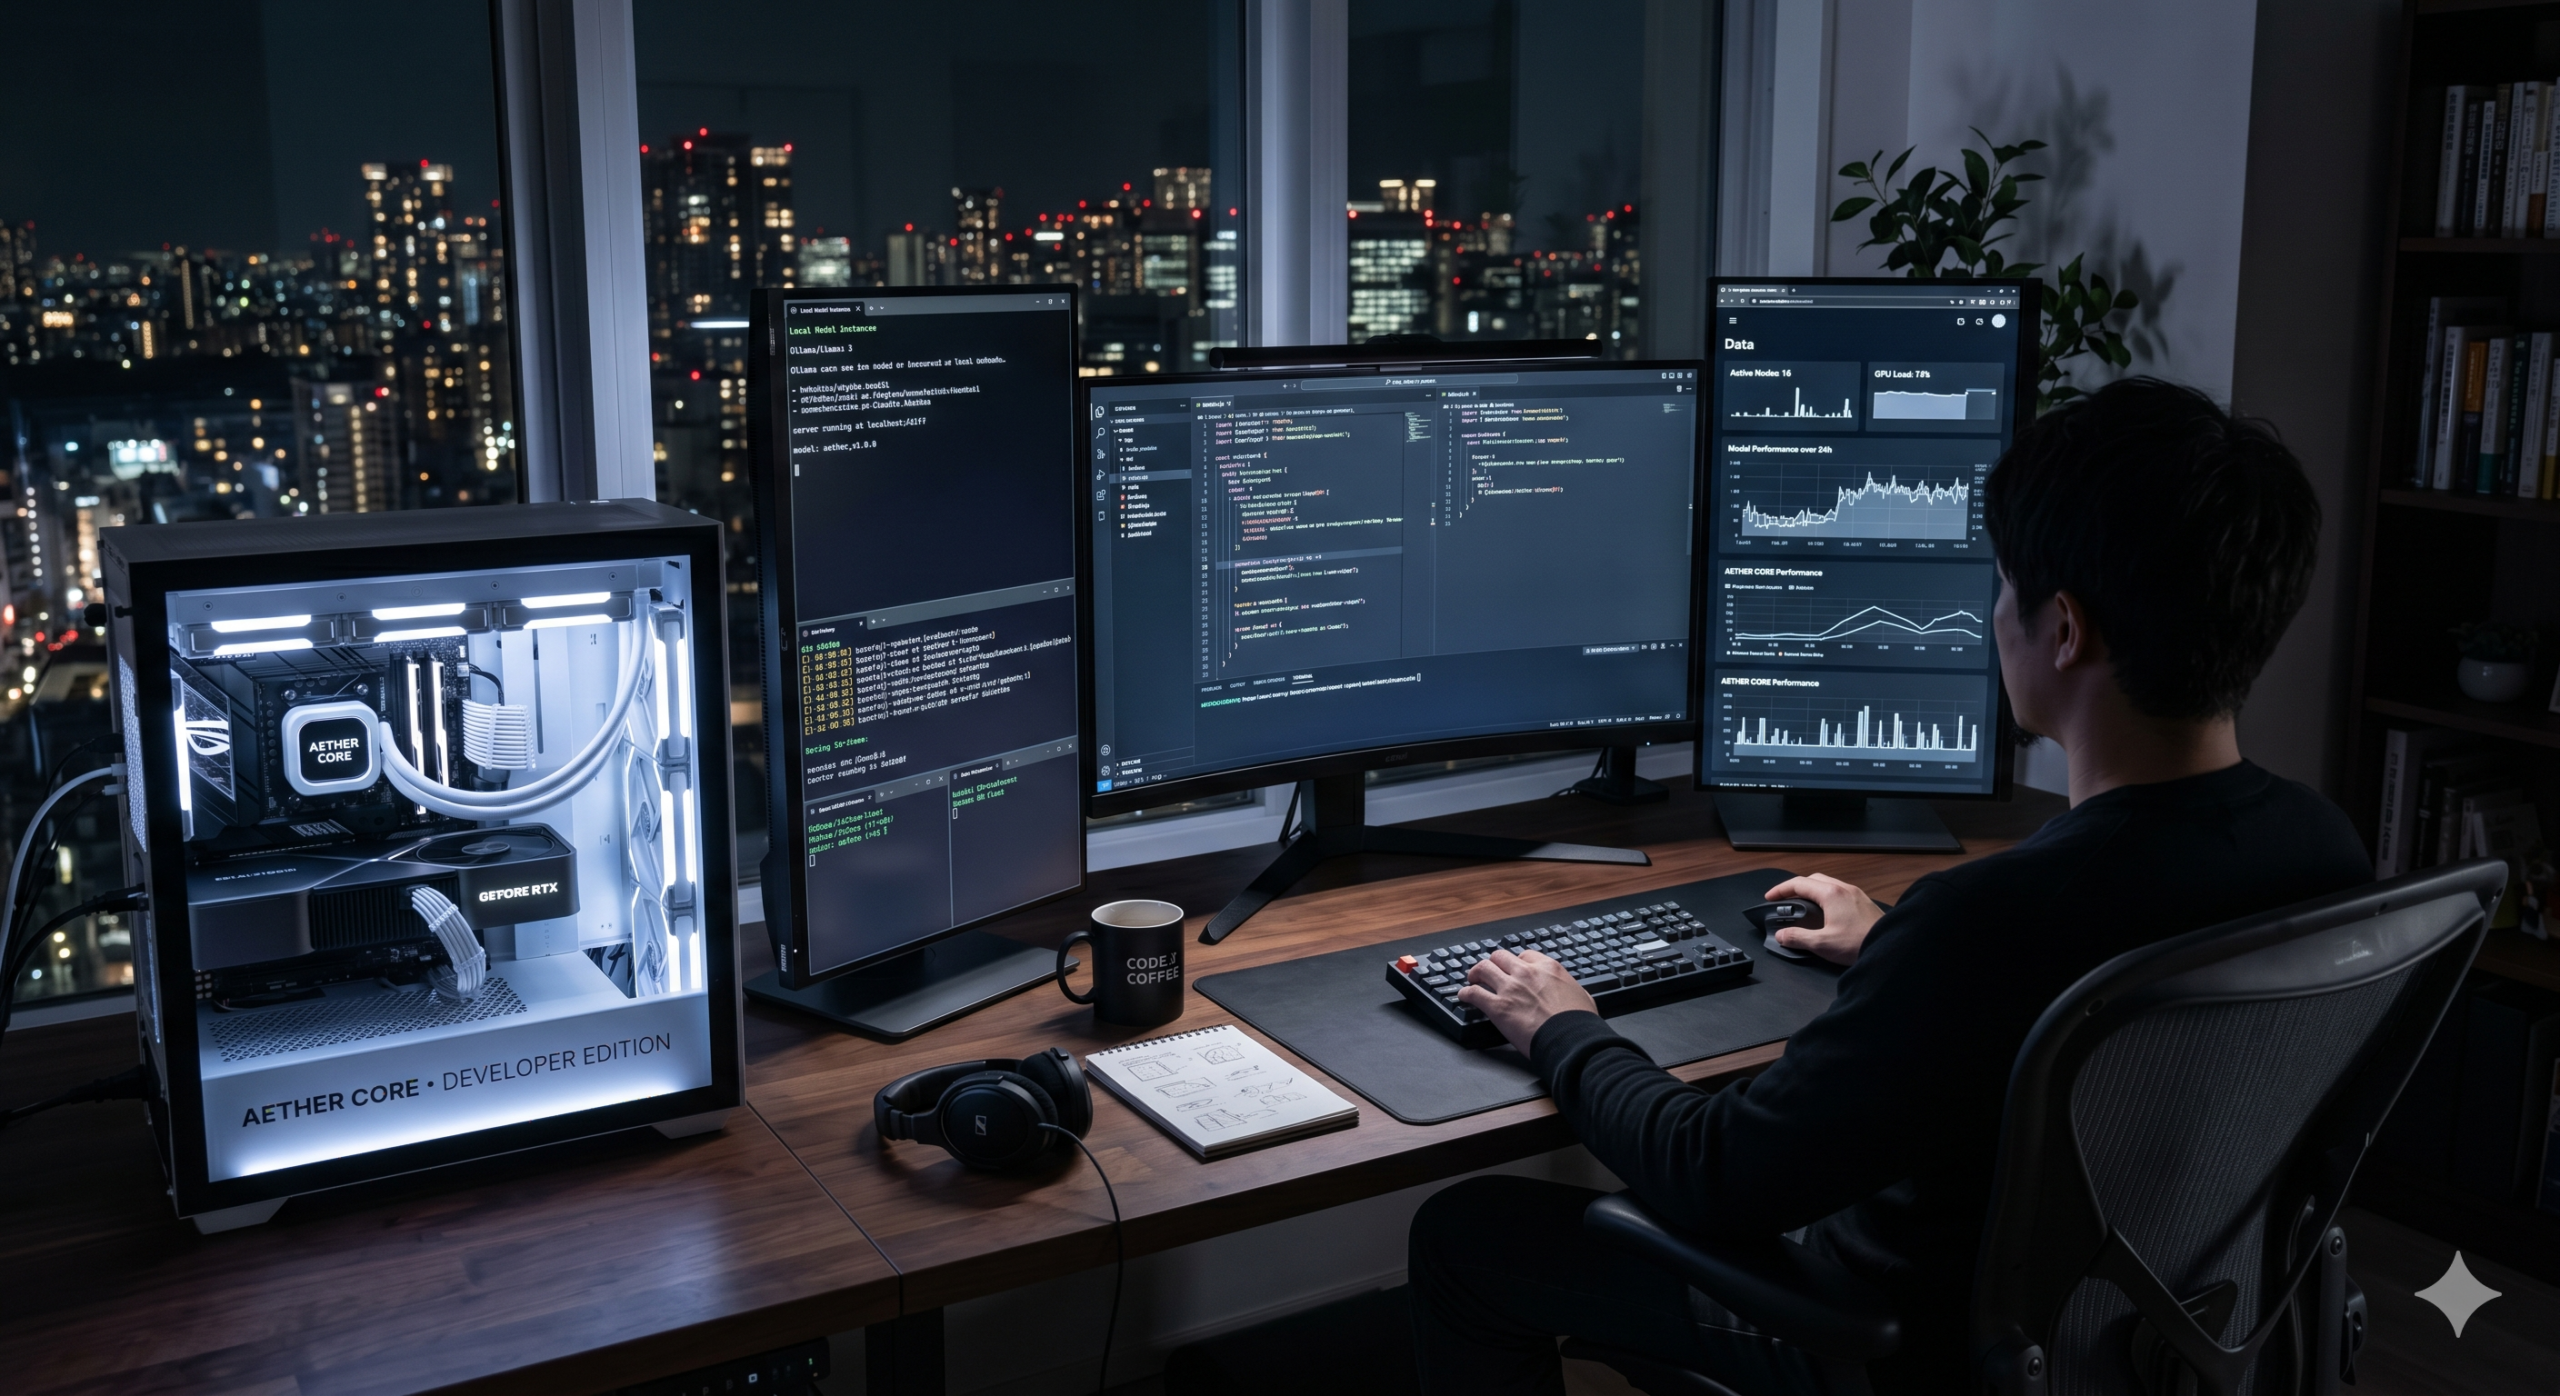
Every conversation about AI writing tools assumes the same architecture: a browser tab, an API key, a monthly bill, and a company somewhere reading every prompt you send it. I run mine differently, and the difference is not ideological. It is practical, and it took less setup than most people assume.
The key is quantization: compressing a model’s internal weights from the sixteen-bit precision they were trained at to four bits or fewer, with a quality hit smaller than the compression ratio would suggest. A model that would need a serious data center GPU to run at full precision fits comfortably on a consumer graphics card once quantized properly, and token-generation speed on decent hardware is usable for real work rather than a novelty demo.
My own stack runs through Ollama, sitting locally as what I think of as a supervisor model, the piece that orchestrates everything else in my content pipeline without a single prompt or draft leaving the machine it runs on. No subscription is attached to it, no rate limit I have to plan around, and no dependency on a service staying up or a company deciding to change its pricing. It is simply there, the way installed software used to be before everything moved to a browser tab and a login screen.
The tradeoff, and there is always a tradeoff, is context window size. Cloud models built to run on data center hardware can hold enormous amounts of text in working memory at once. A model sized to fit on a desktop GPU cannot match that, which means the actual skill in running one of these well is not prompting; it is retrieval, feeding the model exactly the specific piece of information it needs for a given task rather than dumping everything in and hoping it finds the relevant part on its own. Pairing a local vector database with the model lets it pull precise context on demand instead of holding everything in memory simultaneously, which is what makes a small model perform like a much larger one for a narrow, well-defined job.
I don’t think local models are about to replace frontier cloud services for anything genuinely difficult; the reasoning gap between a quantized seven- or eight-billion-parameter model and the largest hosted ones is real, and I am not going to pretend otherwise. What they are good for, and what mine actually does all day, is the unglamorous repetitive middle of a content pipeline, parsing feeds, drafting structure, summarising a source before a human decides whether it is worth writing about at all. That work does not need the smartest model available. It needs one that is always on, costs nothing per call, and never sends a draft anywhere I have not chosen to send it myself.